

Evaluating Qwen3-Coder+Instruct Model#
The new Qwen3 models have arrived! These include the coding model Qwen/Qwen3-Coder-480B-A35B-Instruct and the general-purpose model Qwen/Qwen3-235B-A22B-Instruct-2507. Let’s quickly assess the performance of these two models using the EvalScope model evaluation framework.
Installing Dependencies#
First, install the EvalScope model evaluation framework:
pip install 'evalscope[service]' -U
pip install bfcl-eval # Install bfcl evaluation dependencies
Evaluating Qwen3-Coder Model’s Tool Calling Abilities#
To evaluate the model, we need to access its capabilities through an OpenAI-compatible inference service. Here, we use the API interface provided by DashScope. Note that EvalScope also supports inference evaluation using transformers; for details, refer to the documentation.
Below is the BFCL-v3 benchmark test to evaluate the Coder model’s tool calling abilities. Configuration details are as follows:
import os
from evalscope import TaskConfig, run_task

task_cfg = TaskConfig(
    model='qwen3-coder-plus',
    api_url='https://dashscope.aliyuncs.com/compatible-mode/v1',
    api_key=os.getenv('DASHSCOPE_API_KEY'),
    eval_type='openai_api',  # Use API model service
    datasets=['bfcl_v3'],
    eval_batch_size=10,
    dataset_args={
        'bfcl_v3': {
            'extra_params':{
                # The model refuses to use dots ('.') in function names; set this option to automatically convert dots to underscores during evaluation.
                'underscore_to_dot': True,
                # Whether the model is a function calling model; if true, function-calling-related configs are enabled, otherwise prompt-based bypass is used.
                'is_fc_model': True,
            }
        }
    },
    generation_config={
        'temperature': 0.7,
        'top_p': 0.8,
        'top_k': 20,
        'repetition_penalty': 1.05,
        'max_tokens': 65536,  # Set max generation length
        'parallel_tool_calls': True,  # Enable parallel function calls
    },
    # limit=50,  # Limit number of evaluations for quick testing; remove for full evaluation
    ignore_errors=True,  # Ignore errors; some test cases may be refused by the model
)
run_task(task_cfg=task_cfg)
Output results:
We can see that the model has strong overall tool calling abilities, but there is still significant room for improvement in multi-turn and parallel tool calls.
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| Model            | Dataset   | Metric          | Subset                  |   Num |   Score | Cat.0        |
+==================+===========+=================+=========================+=======+=========+==============+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | live_simple | 257 | 81.7% | AST_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | live_multiple | 1039 | 80.9% | AST_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | live_parallel | 16 | 37.5% | AST_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | live_parallel_multiple | 24 | 41.7% | AST_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | simple | 400 | 95.5% | AST_NON_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | multiple | 200 | 94.5% | AST_NON_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | parallel | 200 | 55% | AST_NON_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | parallel_multiple | 200 | 56% | AST_NON_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | java | 100 | 64% | AST_NON_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | javascript | 50 | 82% | AST_NON_LIVE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | multi_turn_base | 200 | 43% | MULTI_TURN |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | multi_turn_miss_func | 200 | 24% | MULTI_TURN |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | multi_turn_miss_param | 200 | 30.5% | MULTI_TURN |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | multi_turn_long_context | 200 | 38.5% | MULTI_TURN |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | irrelevance | 240 | 84.6% | RELEVANCE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | live_relevance | 17 | 64.7% | RELEVANCE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | live_irrelevance | 881 | 83.4% | RELEVANCE |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
| qwen3-coder-plus | bfcl_v3 | Accuracy ↑ | OVERALL | 4424 | 72% | - |
+------------------+-----------+-----------------+-------------------------+-------+---------+--------------+
Evaluating Qwen3-Instruct Model’s Knowledge and Reasoning Abilities#
Below, we use the simple_qa and chinese_simpleqa benchmarks to evaluate the model’s knowledge base, with Qwen2.5-72B used to judge answer correctness. We also use AIME25 to evaluate complex reasoning abilities. Configuration details:
import os
from evalscope import TaskConfig, run_task

task_cfg = TaskConfig(
    model='qwen3-235b-a22b-instruct-2507',
    api_url='https://dashscope.aliyuncs.com/compatible-mode/v1',
    api_key=os.getenv('DASHSCOPE_API_KEY'),
    eval_type='openai_api',  # Use API model service
    datasets=['simple_qa', 'chinese_simpleqa', 'aime25'],
    eval_batch_size=10,
    generation_config={
        'temperature': 0.7,
        'top_p': 0.8,
        'top_k': 20,
        'max_tokens': 16384,  # Set max generation length
    },
    # limit=20,  # Limit number of evaluations for quick tests; remove for full evaluation
    ignore_errors=True,  # Ignore errors; some test cases may be refused by the model
    stream=True,  # Enable streaming output
    judge={
        'strategy': 'auto',
        'models': { # Judge model configuration
            'model_id': 'qwen2.5-72b-instruct',
            'api_url': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
            'api_key': os.getenv('DASHSCOPE_API_KEY'),
        },
        'generation_config': {
            'temperature': 0.0,
            'max_tokens': 4096
        }
    },
)

run_task(task_cfg=task_cfg)
Output results:
It can be seen that the model demonstrates good reasoning abilities and a high level of knowledge.
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| Model                         | Dataset          | Metric           | Subset               |   Num |   Score | Cat.0   |
+===============================+==================+==================+======================+=======+=========+=========+
| qwen3-235b-a22b-instruct-2507 | aime25           | AveragePass@1    | AIME2025-I           |    15 |  0.6667 | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | aime25           | AveragePass@1    | AIME2025-II          |    15 |  0.6667 | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | aime25           | AveragePass@1    | OVERALL              |    30 |  0.6667 | -       |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | chinese_simpleqa | is_correct       | Chinese Culture      |    20 |  0.65   | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | chinese_simpleqa | is_correct       | Humanities & Social  |    20 |  1      | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | chinese_simpleqa | is_correct       | Engineering & Tech   |    20 |  0.8    | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | chinese_simpleqa | is_correct       | Life, Arts & Culture |    20 |  0.8    | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | chinese_simpleqa | is_correct       | Society              |    20 |  0.9    | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | chinese_simpleqa | is_correct       | Nature & Science     |    20 |  0.8    | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | chinese_simpleqa | is_correct       | OVERALL              |   120 |  0.825  | -       |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| ... (similar for is_incorrect and is_not_attempted) ...
| qwen3-235b-a22b-instruct-2507 | simple_qa        | is_correct       | default              |    20 |  0.6    | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | simple_qa        | is_incorrect     | default              |    20 |  0.35   | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
| qwen3-235b-a22b-instruct-2507 | simple_qa        | is_not_attempted | default              |    20 |  0.05   | default |
+-------------------------------+------------------+------------------+----------------------+-------+---------+---------+
For more supported benchmarks, please see the documentation.
Result Visualization#
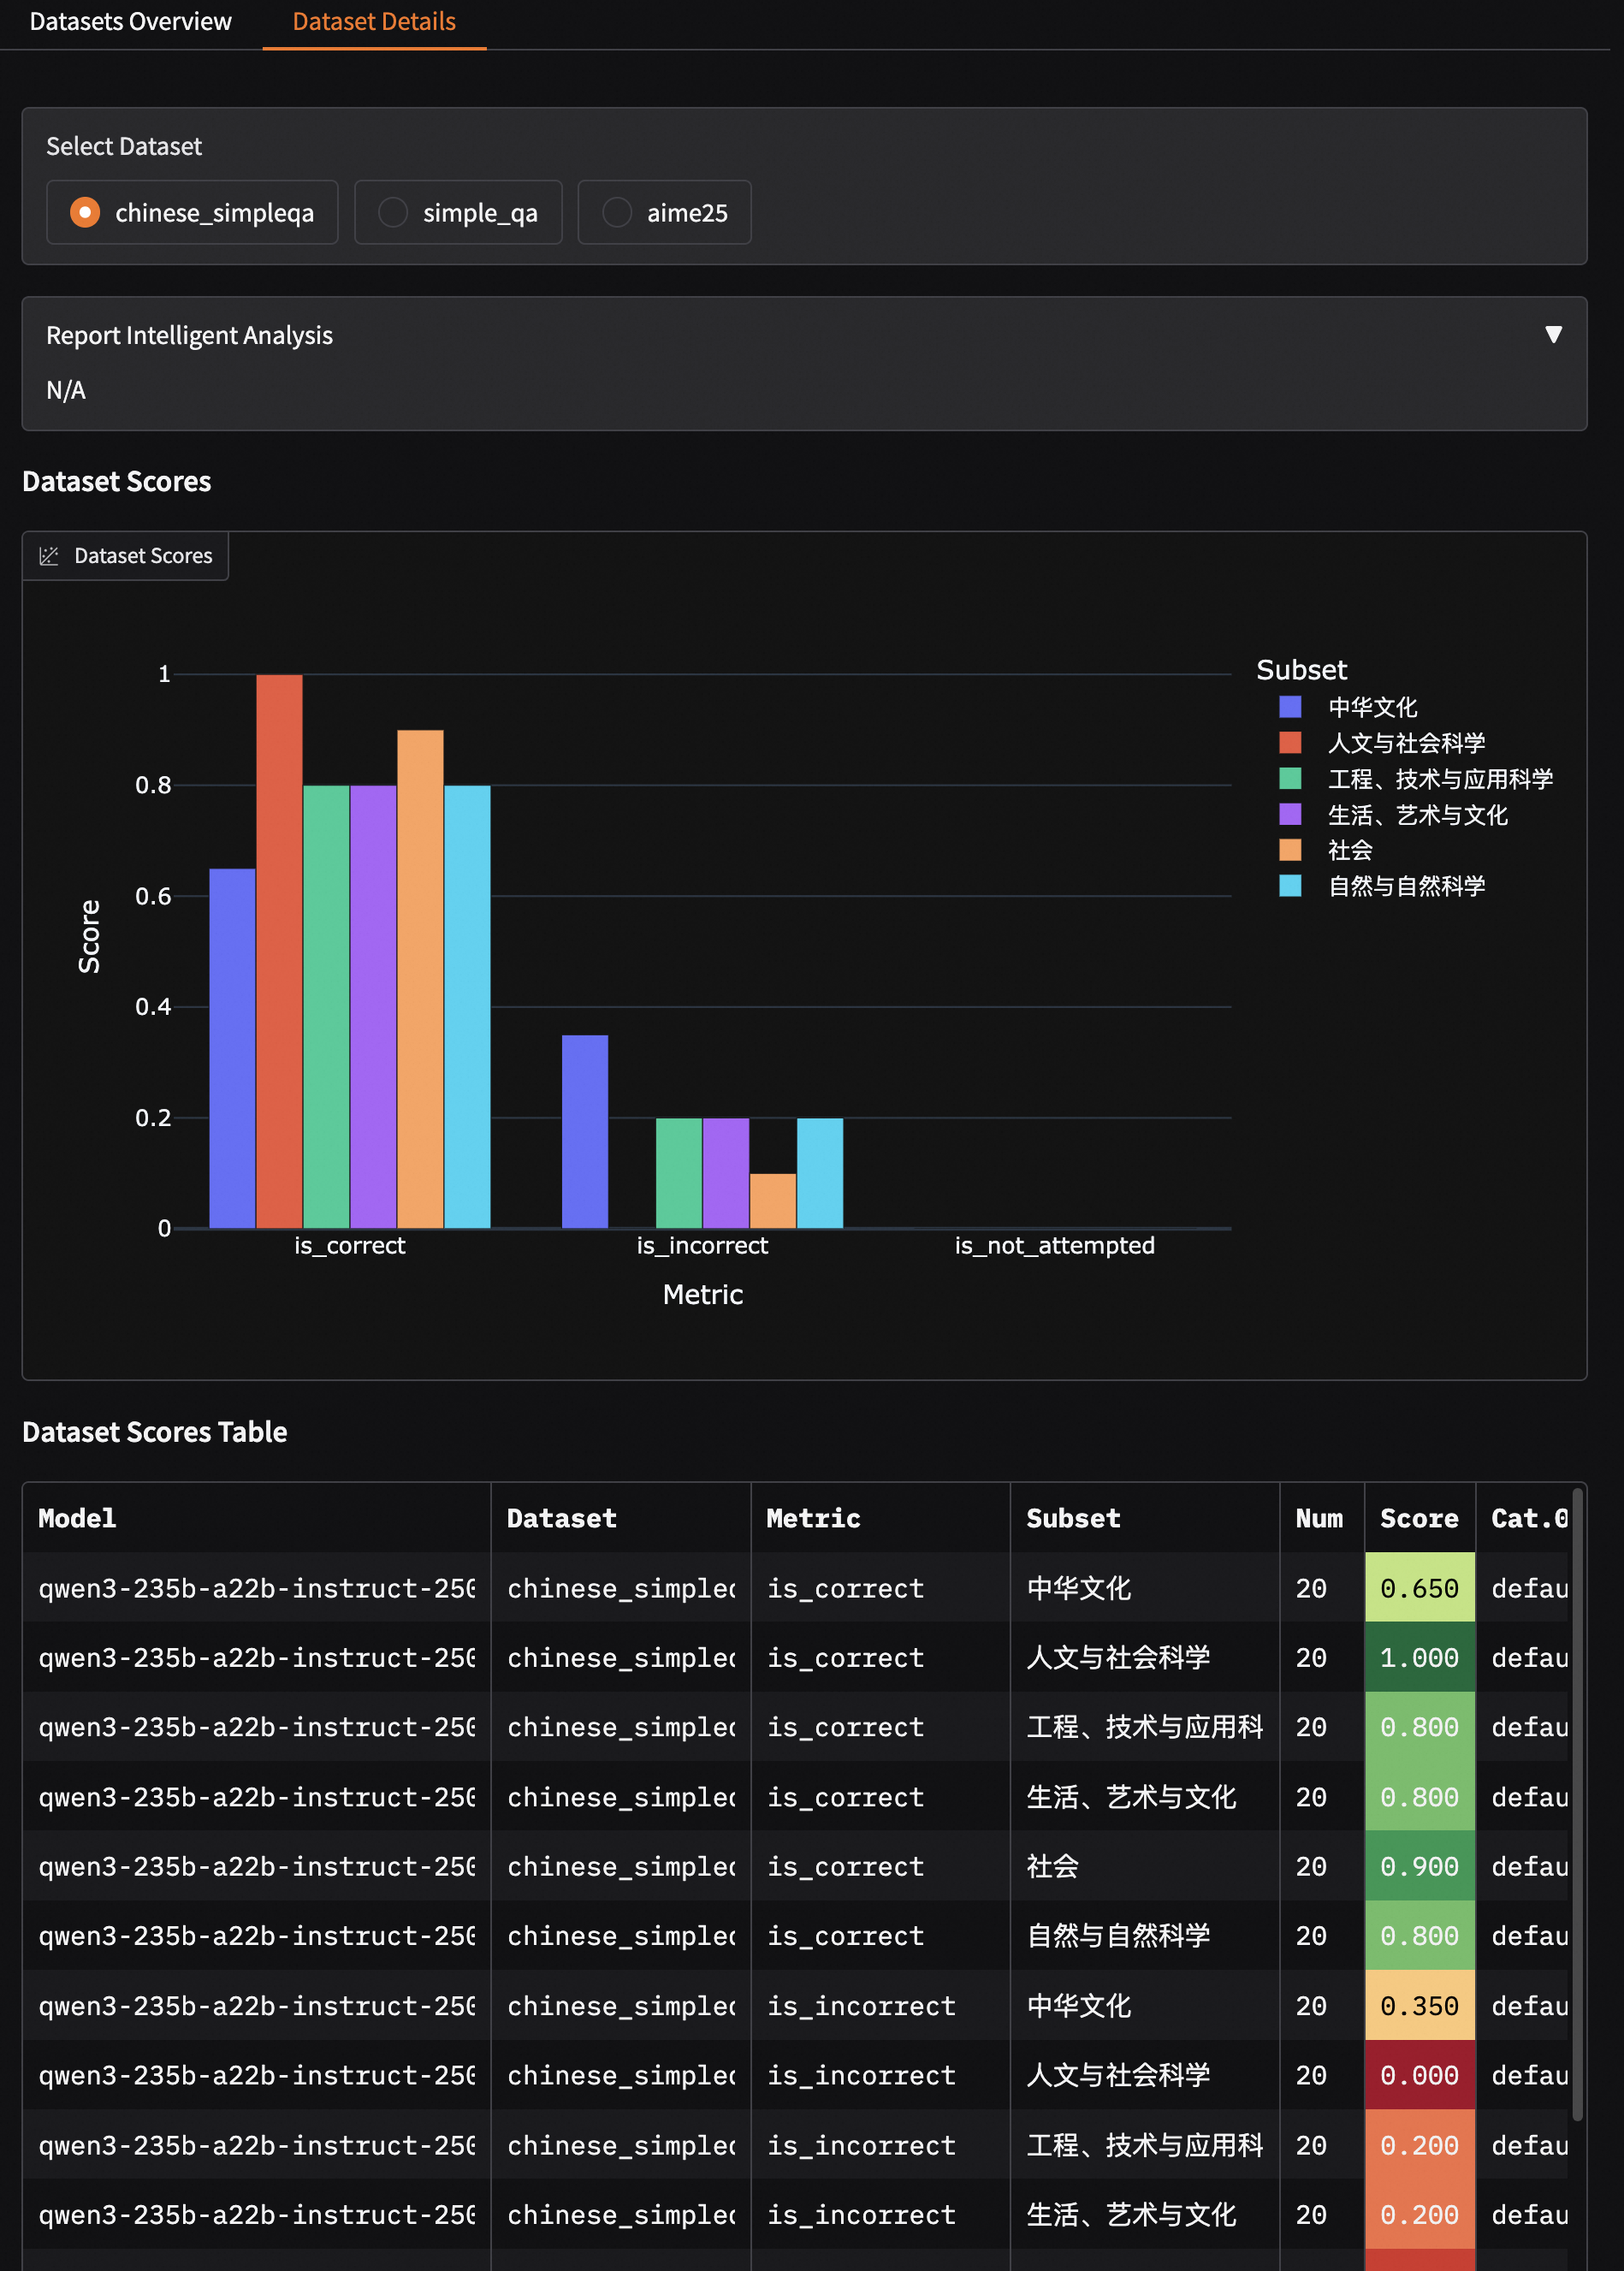
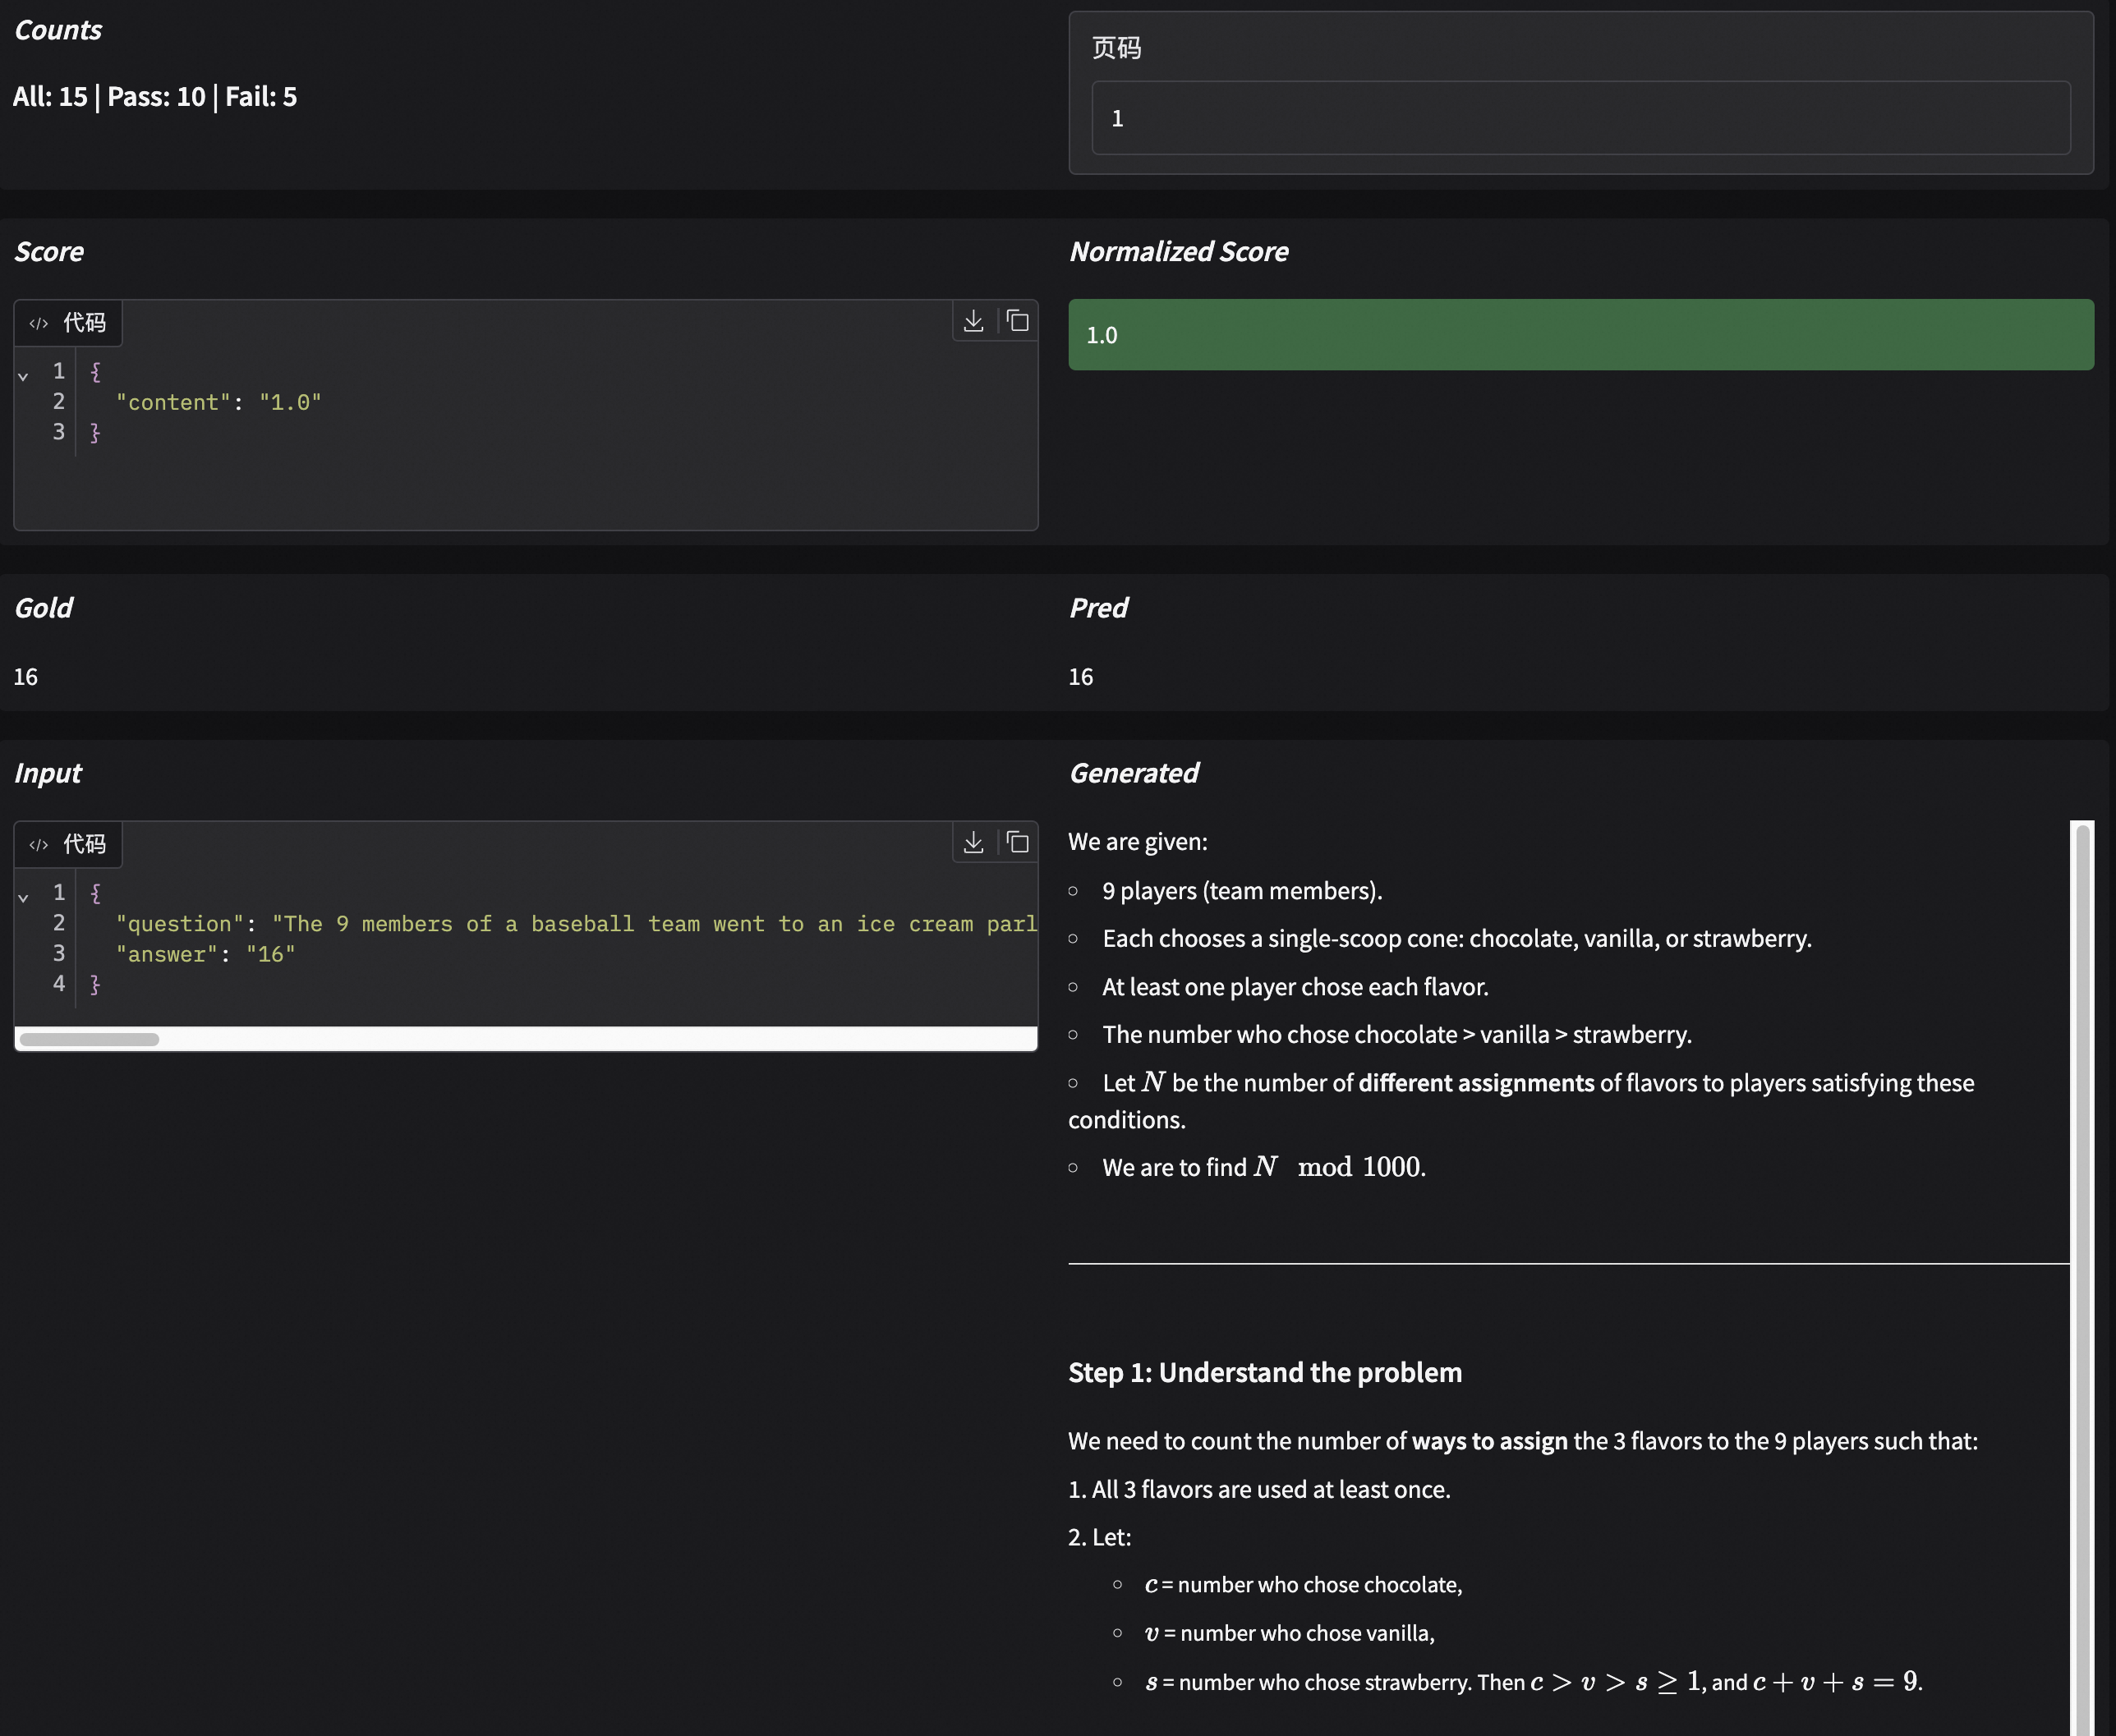
EvalScope supports visualizing results so you can see the model’s specific outputs.
Run the following command to launch the Web dashboard:
evalscope service
Select the evaluation report and click “Load” to view the model’s output for each question, as well as the overall accuracy:
Summary#
This guide introduced how to use the EvalScope framework to evaluate the performance of the two new models: Qwen3-Coder and Qwen3-Instruct. Evaluation included:
Qwen3-Coder Model: Evaluated tool calling abilities using the BFCL-v3 benchmark. The model demonstrated strong overall performance, but there is room for improvement in multi-turn and parallel calls.
Qwen3-Instruct Model: Assessed knowledge and reasoning abilities using the simple_qa, chinese_simpleqa, and AIME25 benchmarks, with outstanding results.
For the complete evaluation process and documentation, please refer to the official EvalScope documentation.